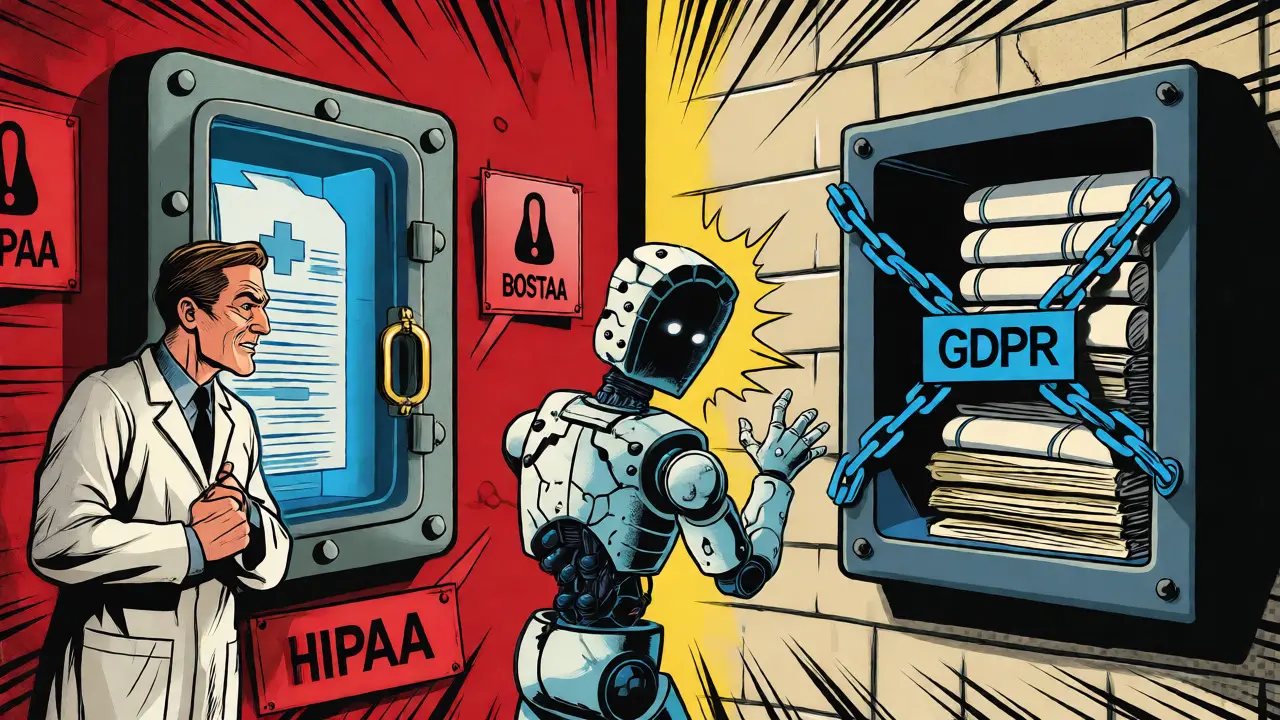
Imagine you’re a hospital administrator in Boston and a bank executive in London. You both want to train a Generative AI model that can draft clinical notes or summarize financial reports with human-like nuance. The problem? Your patient records and customer transactions are too sensitive to move across borders, let alone into a shared cloud bucket. Traditionally, this meant your models remained siloed and underperforming. But there’s a way out of this deadlock: Federated Learning. It lets you build powerful AI together without ever handing over your raw data.
The Core Problem: Data Silos vs. Model Power
Generative AI thrives on diversity. A large language model trained only on medical texts from one region might struggle to understand slang from another. To get the best results, you need massive, varied datasets. But regulations like GDPR in Europe and HIPAA in the US make centralizing that data a legal nightmare. Federated learning flips the script. Instead of moving data to the model, it moves the model to the data. This approach, formalized by researchers at Google and now widely adopted in enterprise settings, allows distributed entities-think devices, servers, or entire organizations-to jointly train AI models while keeping their raw information local.
How Federated Learning Actually Works
The process is surprisingly intuitive once you strip away the jargon. Here is the standard lifecycle used in most modern implementations:
- Local Training: Each participant (a "client") takes the current version of the global AI model and trains it briefly using their own private data. For example, your smartphone keyboard learns your typing habits locally.
- Update Generation: The client calculates changes to the model’s parameters (weights) based on what it learned. Crucially, it does not send the raw text or images back; it sends only these mathematical updates.
- Secure Aggregation: These updates travel to a central server. The server combines them-often using advanced cryptography-to create an improved global model.
- Distribution: The updated global model is sent back to all participants, who then use it for the next round of local training.
This cycle repeats until the model reaches the desired accuracy. Because the raw data never leaves the source device or server, you satisfy strict data sovereignty requirements. In automotive manufacturing, for instance, vehicle telemetry collected in Germany stays in Germany, even if the car manufacturer’s headquarters are in Detroit.
Layered Privacy: More Than Just Not Sending Data
You might wonder: if I’m sending model updates, could someone reverse-engineer my data? Potentially, yes. That’s why federated learning doesn’t rely on obscurity alone. It employs a layered defense system involving four primary techniques to ensure true privacy preservation.
| Technique | What It Does | Why It Matters |
|---|---|---|
| Differential Privacy (DP) | Adds statistical noise to model updates. | Makes it mathematically difficult to trace an update back to a specific user or record. |
| Homomorphic Encryption (HE) | Allows computation on encrypted data. | The central server processes updates without ever decrypting them. |
| Secure Multi-Party Computation (SMPC) | Lets parties compute results jointly without revealing inputs. | No single participant can view another’s individual contribution. |
| Trusted Execution Environments (TEEs) | Isolates computations in hardware enclaves. | Prevents tampering or unauthorized access during processing. |
These methods work together. Differential privacy protects against inference attacks, while homomorphic encryption ensures that even if the aggregation server is compromised, the data remains unreadable. This combination creates a robust shield that traditional centralized training often lacks.
Why Generative AI Needs Federation
Generative AI, unlike simple classification models, produces new content-text, images, code. This makes it particularly valuable but also risky when it comes to privacy. If a model memorizes a rare patient name or a unique transaction pattern, it might accidentally leak that info in its output. Federated learning mitigates this by ensuring the model learns patterns rather than memorizing specific instances from a centralized dataset.
Moreover, federation enhances creativity. By pooling knowledge from diverse sources-say, hospitals in Asia, banks in Europe, and retailers in North America-the model encounters a wider variety of contexts. This diversity leads to more nuanced, innovative outputs. A generative model trained via federation understands that "apple" means fruit in one context and tech giant in another, simply because it saw those variations across different private datasets.
The Hidden Risks: It’s Not Perfect
Don’t let the marketing fool you: federated learning isn’t a magic bullet. It introduces new attack surfaces. Adversaries can attempt "gradient inversion" attacks, where they analyze the shared model updates to reconstruct parts of the original training data. Malicious participants might also inject "poisoned" data to skew the model’s behavior.
To combat this, organizations must invest in strong cryptography and anomaly monitoring. You need to verify that the aggregation server is trustworthy and that the updates coming in look statistically normal. If one participant suddenly sends a wildly different update, it could be a sign of an attack or bad data. Security here is end-to-end; it requires securing the devices, the communication channels, and the aggregation logic itself.
Real-World Applications Beyond Tech Giants
While Google pioneered this with Android keyboards, the real value lies in regulated industries.
- Healthcare: Hospitals can collaborate on diagnostic AI models without sharing patient charts. This accelerates research into rare diseases where no single hospital has enough cases.
- Finance: Banks can jointly train fraud detection models. Since fraud patterns evolve quickly, sharing insights without exposing customer balances gives everyone a competitive edge against criminals.
- Automotive: Car manufacturers can improve autonomous driving algorithms by learning from millions of vehicles worldwide, respecting local data laws in each country.
In each case, the goal is the same: leverage collective intelligence while respecting individual privacy boundaries.
Implementation Checklist for Leaders
If you’re considering federated learning for your organization, keep these practical steps in mind:
- Audit Your Data: Identify which datasets are highly sensitive and legally restricted. These are your best candidates for federation.
- Choose Your Privacy Layer: Decide between differential privacy (easier to implement, slight accuracy loss) and homomorphic encryption (higher security, higher computational cost).
- Plan for Heterogeneity: Expect non-IID data (data that isn’t uniformly distributed). Your clients will have different data profiles, so your aggregation algorithm needs to handle this variance.
- Monitor for Attacks: Set up alerts for unusual model updates. Implement validation checks before aggregating contributions.
Does federated learning completely eliminate privacy risks?
No, it significantly reduces risk but doesn't eliminate it entirely. While raw data stays local, model updates can still reveal information through gradient inversion attacks. However, combining federated learning with differential privacy and encryption makes reconstruction extremely difficult and computationally expensive for attackers.
Is federated learning slower than centralized training?
It can be. Communication overhead is a major challenge because models must be sent back and forth repeatedly. Additionally, if some participants have slow connections or older hardware, they become bottlenecks. Asynchronous training methods help mitigate this, but latency is generally higher than in centralized setups.
Can competitors really trust each other in a federated setup?
Trust is minimized, not required. Secure multi-party computation and trusted execution environments allow competitors to contribute to a model without revealing their proprietary data strategies to each other. The technical architecture enforces confidentiality, reducing the need for interpersonal trust.
What happens if a participant drops out mid-training?
Most federated learning frameworks are designed to be fault-tolerant. If a client disconnects, the server simply waits for other responses or proceeds with available updates, depending on the synchronization strategy (synchronous vs. asynchronous). The global model continues to learn from the remaining active participants.
Do I need specialized hardware for federated learning?
Not necessarily for basic implementations, but homomorphic encryption and secure aggregation require significant computational power. Many enterprises use dedicated servers or cloud instances optimized for cryptographic operations to handle the aggregation step efficiently.