Category: Science & Research
Tamara Weed, Sep, 17 2026
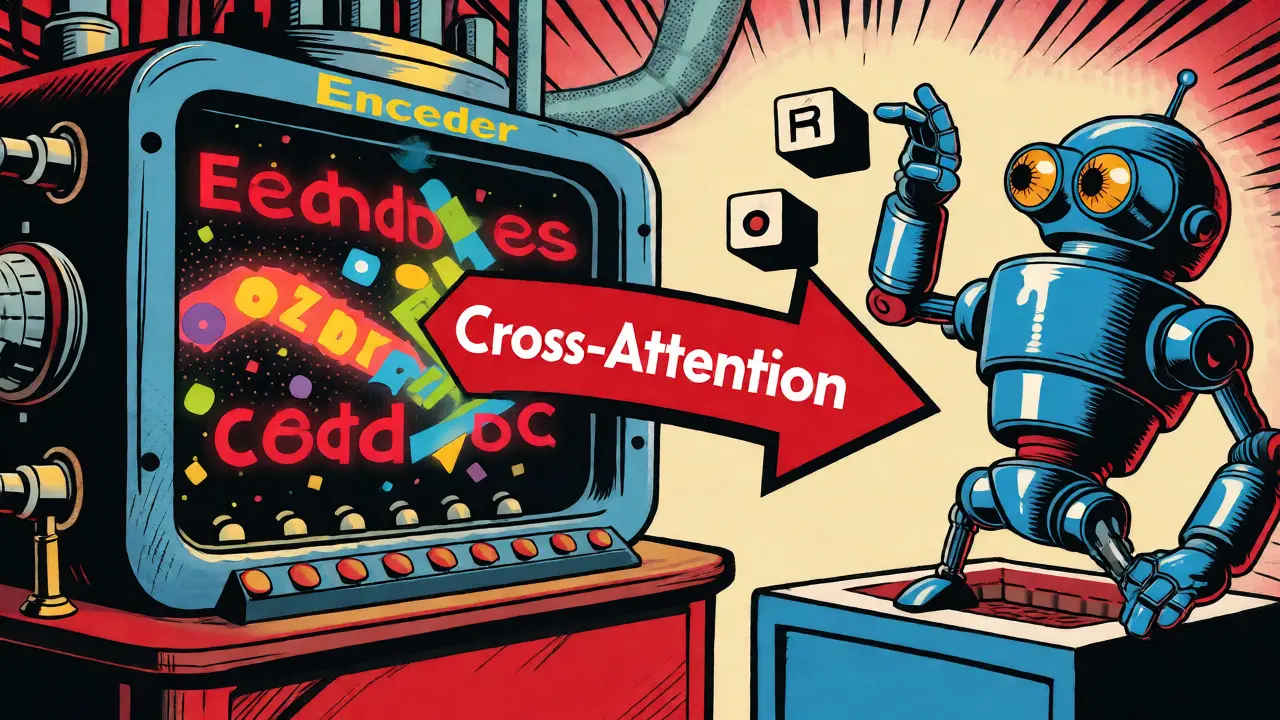
Discover how cross-attention enables encoder-decoder transformers to condition outputs on input context. Learn the mechanics, differences from self-attention, and applications in translation and multimodal AI.
Categories:
Tags:
Tamara Weed, Sep, 10 2026
Discover how diffusion models like Stable Diffusion amplify gender and race biases. Learn why AI image generators skew demographics and what businesses must do to mitigate risks.
Categories:
Tags:
Tamara Weed, Sep, 9 2026
Discover the best long-context benchmarks for LLMs in 2025. Compare LongBench Pro, InfiniteBench, and HELM to evaluate model performance on 8k to 1M+ token inputs.
Categories:
Tags:
Tamara Weed, Aug, 29 2026
Discover why English-centric alignment fails in multilingual LLMs. Learn how bias shifts across languages and how to audit your models for true global fairness.
Categories:
Tags:
Tamara Weed, Aug, 26 2026
Discover why Pre-Norm is the standard for stable LLM training. We compare gradient flow, activation risks, and implementation tips for deep Transformer architectures.
Categories:
Tags:
Tamara Weed, Aug, 20 2026
Discover how training data, selection errors, and algorithm design create bias in generative AI. Learn practical strategies for mitigation and the importance of responsible AI development.
Categories:
Tags:
Tamara Weed, Aug, 12 2026
Discover how sampling choices like temperature and nucleus sampling directly influence LLM accuracy and hallucination rates. Learn practical strategies to optimize your AI outputs.
Categories:
Tags:
Tamara Weed, Aug, 2 2026
Explore the key differences between BERT and GPT architectures. Learn why encoder-only models excel at understanding while decoder-only models dominate text generation, and how to choose the right one for your NLP project.
Categories:
Tags:
Tamara Weed, Aug, 2 2026
Explore the key differences between BERT and GPT architectures. Learn how encoder-only and decoder-only models impact NLP tasks, performance, and implementation costs.
Categories:
Tags:
Tamara Weed, Jul, 18 2026
Discover how to detect fabricated references in LLM outputs. Learn why AI creates ghost citations, the risks to academic integrity, and tools like CERCA to verify sources.
Categories:
Tags:
Tamara Weed, Jul, 1 2026
Discover why Large Language Models excel at diverse tasks through transfer learning, generalization, and emergent abilities. Learn how these mechanisms work, their benefits, limitations, and practical implementation tips for 2026.
Categories:
Tags:
Tamara Weed, Jun, 28 2026
Explore how stochastic depth regularizes deep transformer-based LLMs by randomly dropping layers. Learn about neural collapse, implementation strategies, and advanced techniques like LAAT and ReplaceMe for better generalization.
Categories:
Tags: