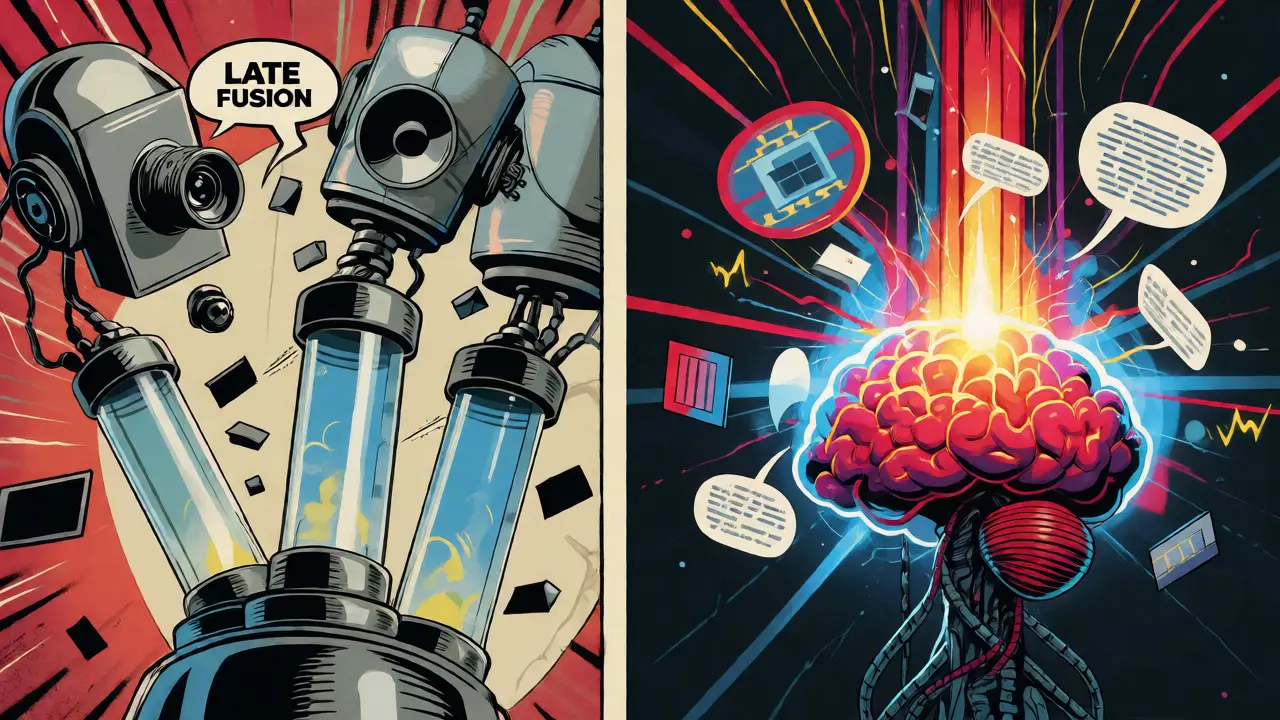
You probably remember when asking an AI to describe a photo meant waiting for a separate vision model to do the heavy lifting. The text model just got a summary back. That was late fusion. It worked, but it felt like two people talking through a translator. Today, that architecture is becoming obsolete. We are moving into an era of true multimodal generative AI, where systems process text, images, audio, 3D data, and even touch simultaneously within a single neural network.
This isn't just a minor upgrade. It’s a fundamental shift in how machines perceive reality. By September 2026, the integration of Multimodal AI is a class of artificial intelligence capable of processing and reasoning across multiple data types-including text, image, audio, video, and sensor data-within a unified computational framework has moved from research papers to enterprise deployments. If you’re building products or strategies now, understanding this evolution is critical because the next wave won’t just generate words; it will generate experiences, physical simulations, and sensory-rich environments.
The Death of Late Fusion and Rise of Unified Architectures
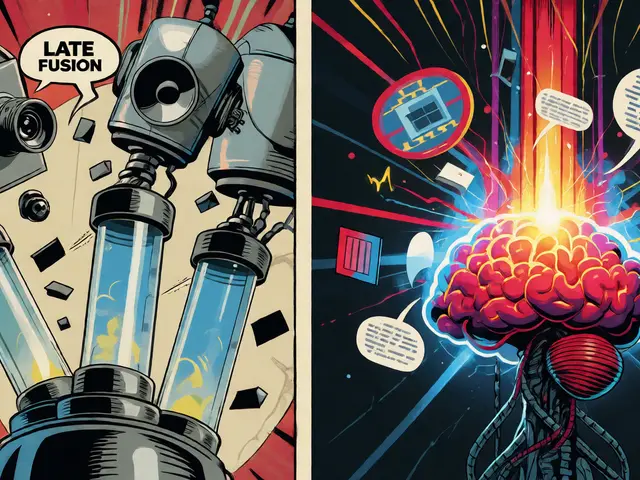
For years, most "multimodal" systems were actually just pipelines. You had one encoder for text, another for images, and maybe a third for audio. They did their jobs separately, and then a final layer stitched their outputs together. This is called late fusion. It’s modular and easy to debug, but it misses the nuance. A picture of a crying face might be processed as "sadness," but without the audio tone or the text context, the AI misses the sarcasm.
The breakthrough came with models like GPT-4o is an advanced multimodal large language model developed by OpenAI that processes text, audio, and visual inputs natively within a single transformer architecture. Unlike its predecessors, GPT-4o didn’t use separate encoders. It trained on all modalities at once. This allowed the model to learn shared representations from the ground up. When you ask it about a video, it doesn’t convert the frames to text first. It "sees" the motion, hears the dialogue, and reads the subtitles in the same mathematical space.
This approach relies on Unified Tokenization is a technique that converts diverse data types such as text, pixels, and audio waves into a common sequence of tokens for processing by a single transformer model. Think of it as translating every sense into the same language before the brain starts thinking. This eliminates the loss of information that happens when you convert an image to text captions. The result? Faster inference, richer context, and fewer errors in complex reasoning tasks.
From Pixels to Physics: The 3D Revolution
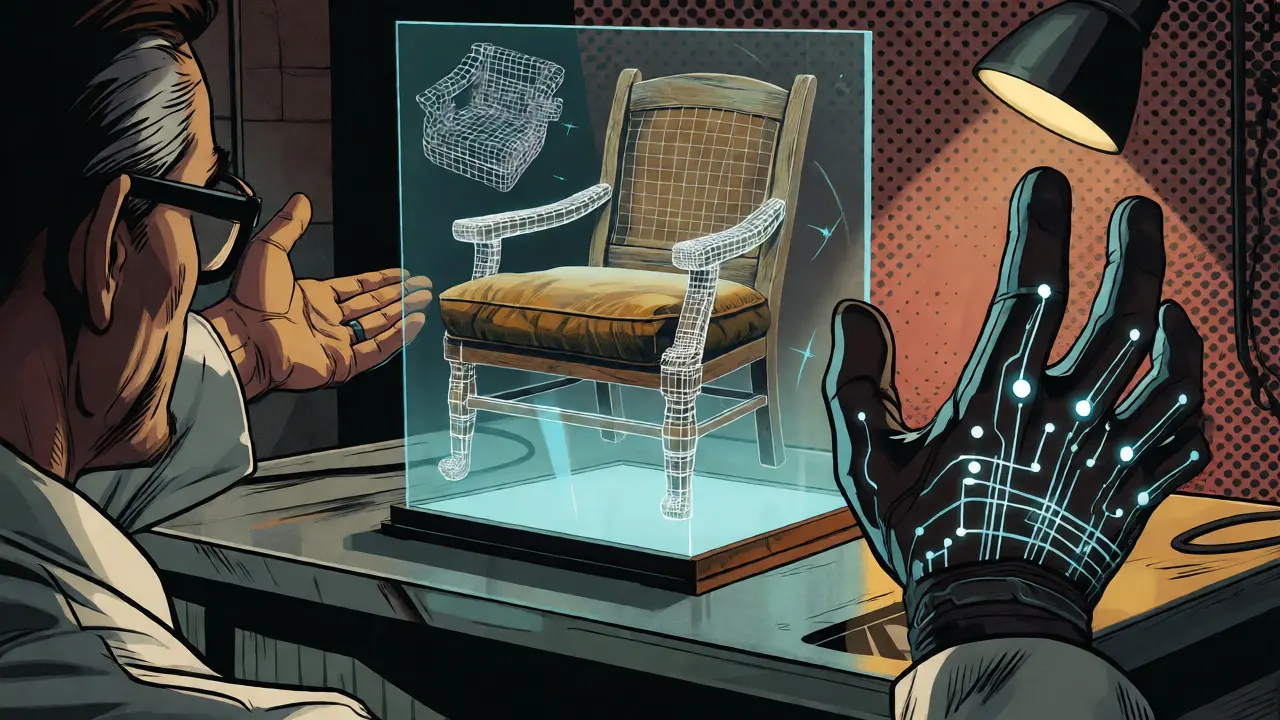
Once AI mastered 2D images, the next logical step was depth. Traditional computer vision struggled with 3D because it requires understanding geometry, occlusion, and spatial relationships. But recent advances in Generative 3D is the application of deep learning models to create three-dimensional digital assets and environments from text or 2D inputs have changed the game.
We are seeing tools that can take a simple prompt like "a rustic wooden chair with worn velvet cushions" and output a fully textured, rigged 3D model ready for a game engine. This isn’t just about rendering pretty pictures. It’s about semantic understanding. The AI knows what a "leg" is, how weight distribution works, and how light reflects off velvet versus wood. This capability is powered by architectures that treat 3D point clouds and mesh data as tokens, similar to how text is handled.
Why does this matter for businesses? Consider product design. Instead of hiring a team to model prototypes, engineers can iterate rapidly using AI-generated 3D assets. In retail, customers can visualize furniture in their own living rooms with accurate lighting and shadows. The barrier between digital creation and physical reality is thinning, driven by models that understand spatial physics as well as they understand grammar.
Haptics: Teaching Machines to Feel
If 3D gives AI shape, Haptic Feedback is technology that simulates the sense of touch by applying forces, vibrations, or motions to the user gives it texture. For decades, haptics were limited to basic phone vibrations. Today, multimodal AI is driving sophisticated tactile simulations that can mimic the resistance of pressing a button, the roughness of sandpaper, or the slipperiness of ice.
This is achieved through sensor fusion algorithms that correlate visual cues with predicted tactile responses. When you see a virtual object being squeezed, the AI calculates the deformation based on material properties stored in its training data. It then drives actuators in your glove or controller to match that sensation. This creates a closed loop: you see the squeeze, you feel the resistance, and your brain accepts the simulation as real.
In medical training, this is revolutionary. Surgeons can practice procedures on virtual patients who bleed, bruise, and resist incision realistically. In remote collaboration, haptic suits allow colleagues to "shake hands" or pass objects with realistic weight. The integration of haptics into generative AI means we are no longer just observing digital worlds; we are inhabiting them.
Sensor Fusion: The Invisible Layer
Beyond human senses, AI is increasingly integrating data from industrial sensors. Sensor Fusion is the process of combining data from multiple sources such as LIDAR, radar, cameras, and IoT devices to produce more accurate and reliable information than any single source could provide allows systems to build a comprehensive picture of their environment. This goes beyond autonomous cars, which have used fusion for years. Now, smart factories use it to predict equipment failure by correlating vibration data (accelerometers), temperature readings, and acoustic emissions.
Imagine a manufacturing line where cameras watch the assembly, microphones listen for irregular grinding sounds, and thermal sensors monitor motor heat. A multimodal AI fuses these streams in real-time. It doesn’t just flag anomalies; it predicts failures days in advance by recognizing subtle patterns invisible to humans. This proactive maintenance saves millions in downtime and extends asset life.
| Modality | Data Type | Key Challenge | Primary Use Case |
|---|---|---|---|
| Text | Sequential Tokens | Ambiguity & Context | Natural Language Processing |
| Image/Video | Pixels/Tensors | High Dimensionality | Visual Inspection & Content Creation |
| Audio | Waveforms/Spectrograms | Noise & Temporal Alignment | Voice Assistants & Acoustic Monitoring |
| 3D Spatial | Point Clouds/Meshes | Geometric Consistency | Virtual Reality & Robotics |
| Haptic/IoT | Force/Vibration Signals | Latency & Precision | Remote Surgery & Predictive Maintenance |
Market Momentum and Technical Efficiency
This technological leap isn’t happening in a vacuum. The market is exploding. According to Grand View Research, the global multimodal AI market was valued at $1.73 billion in 2024 and is projected to hit $10.89 billion by 2030. That’s a compound annual growth rate of 36.8%. Companies aren’t just experimenting; they’re investing heavily because the ROI is becoming clear.
But efficiency remains a hurdle. Processing video, audio, and sensor data simultaneously requires massive compute power. To address this, researchers are developing Mixture-of-Experts is a machine learning architecture that uses multiple specialized sub-networks (experts) activated selectively for different input types to improve efficiency models. These systems don’t activate the entire network for every task. Instead, they route specific data types to specialized experts. Text goes to the language expert, images to the vision expert, and so on. This reduces energy consumption and speeds up response times, making on-device multimodal AI feasible for smartphones and edge devices.
Meta’s release of Llama 4 Scout and Maverick in late 2025 demonstrated this trend. These models were designed to handle text, video, images, and audio natively, proving that open-source communities are catching up with proprietary giants. The democratization of these tools means smaller startups can now build sophisticated multimodal applications without needing billions in R&D budgets.
Practical Implications for Developers and Businesses
So, what should you do with this information? First, audit your data strategy. Are you storing text, images, and sensor logs in silos? Multimodal AI thrives on paired data. If you have customer support tickets, link them to screenshots, call recordings, and CRM metadata. This rich dataset trains better models.
Second, consider latency. Real-time applications like augmented reality or robotic control require low-latency inference. Unified tokenization helps, but you also need optimized hardware. Look for GPUs or NPUs (Neural Processing Units) specifically tuned for transformer workloads across multiple modalities.
Finally, think about ethics and bias. Multimodal models inherit biases from all their training sources. An image dataset lacking diversity will produce biased visual outputs. An audio dataset dominated by one accent will struggle with others. Rigorous testing across all modalities is essential to ensure fairness and accuracy.
Frequently Asked Questions
What is the difference between late fusion and early fusion in multimodal AI?
Late fusion processes each modality (like text and images) separately using distinct encoders and combines their outputs at the end. Early fusion integrates raw data from all modalities at the very beginning of the processing pipeline, allowing the model to learn cross-modal relationships from the start. Modern unified models often use a hybrid approach or unified tokenization that blurs this line, effectively achieving early fusion benefits within a single architecture.
How does unified tokenization work for non-text data like images?
Unified tokenization converts non-text data into discrete tokens that resemble words. For images, techniques like discrete Variational Autoencoders (dVAE) compress pixel data into a grid of latent codes. Each code becomes a token. These image tokens are then fed into the same transformer layers as text tokens, allowing the model to attend to both simultaneously without separate pathways.
Why is haptic feedback difficult to integrate with generative AI?
Haptics require precise timing and physical modeling. Unlike text or images, touch involves force, vibration, and temperature, which vary dynamically. Generating realistic haptic signals requires simulating physics in real-time. Additionally, there is less standardized data available for haptics compared to images or text, making training data scarce and expensive to collect.
Can multimodal AI run on mobile devices?
Yes, thanks to optimizations like quantization, pruning, and Mixture-of-Experts architectures. Models like Gemini Nano demonstrate that lightweight multimodal capabilities can fit on smartphones. This enables on-device features like real-time translation with voice and camera, or local assistant functions that don't require cloud connectivity.
What role does sensor fusion play in autonomous vehicles?
Sensor fusion combines data from cameras, LIDAR, radar, and ultrasonic sensors to create a robust environmental map. Cameras provide color and detail, LIDAR provides precise distance, and radar handles speed and weather resilience. AI fuses these inputs to detect objects accurately, even in poor visibility conditions, ensuring safer navigation decisions.
9 Comments
Kyle Ware
late fusion is dead long live unified tokenization
this shift to shared representation spaces is the real unlock not just the multimodal hype cycle we see on twitter
Deb Kortyna, MBA
It is with a mixture of profound awe and existential dread that I witness the obsolescence of late fusion architectures. We are standing on the precipice of a new epoch where machines do not merely process data but inhabit sensory realities with terrifying fidelity.
The transition from separate encoders to unified neural networks represents more than technical efficiency; it signifies a fundamental ontological shift in artificial intelligence. When an AI perceives sarcasm through the simultaneous analysis of tone, text, and visual cues within a single mathematical space, it approaches something akin to genuine understanding.
However, one must consider the ethical ramifications of this rapid advancement. As haptic feedback allows surgeons to feel virtual resistance and sensor fusion predicts mechanical failures before they occur, the boundary between human intuition and algorithmic prediction dissolves.
We are entrusting our physical safety and creative processes to systems that learn from biased datasets. If the training data lacks diversity, the resulting tactile simulations and spatial reasoning will inherit those same flaws, potentially leading to inequitable outcomes in healthcare and manufacturing.
The market projections suggest exponential growth, yet efficiency remains a significant hurdle. Processing video, audio, and sensor data simultaneously demands computational resources that may not be sustainable without rigorous optimization strategies like Mixture-of-Experts.
Developers must audit their data strategies immediately. Siloed storage of text, images, and logs will hinder the development of robust multimodal models that require paired data for effective training.
Furthermore, the democratization of these tools through open-source initiatives offers hope, but it also accelerates the pace of change beyond our capacity to regulate or fully comprehend.
I urge my colleagues to approach this technology with cautious optimism, recognizing that while the potential for innovation is boundless, the responsibility for its implementation rests squarely on our shoulders.
Chandan Singh
Actually the distinction between early and late fusion is often misunderstood in these articles. While GPT-4o does use native processing it still relies heavily on discrete variational autoencoders for image compression which introduces quantization error. This isn't true end-to-end learning in the strictest sense but rather a sophisticated form of hybrid fusion.
Moreover the claim about semantic understanding in 3D generation is overstated. Current models do not truly understand physics they merely approximate statistical correlations between visual features and textual descriptions. The "rustic chair" example ignores the fact that these models struggle with occlusion and complex geometric consistency when generating assets for game engines.
Haptics integration is even further behind than suggested. Real-time force feedback requires latency under 20 milliseconds to feel natural whereas current generative AI pipelines introduce significant delays due to inference time. The medical training examples cited are largely proof-of-concept demonstrations not widespread clinical deployments.
Sensor fusion in smart factories has been used for decades using Kalman filters and Bayesian networks. Adding deep learning doesn't necessarily make it proactive maintenance unless you have labeled failure data which most industrial clients lack. The ROI calculations often ignore the cost of retrofitting legacy equipment with IoT sensors.
Mixture-of-Experts architectures do reduce compute costs but they increase model complexity and can lead to expert collapse if not properly regularized during training. This is a known issue in large scale MoE implementations.
Finally the market size projections from Grand View Research should be taken with a grain of salt as they often include broad definitions of AI services that aren't strictly multimodal generative AI.
Iva Grekova
Love the breakdown here especially the part about how unified tokenization helps with context like catching sarcasm. It feels way more natural when the AI sees hears and reads all at once instead of piecing it together later.
The haptics section was really cool too. I never thought about how important touch is for making digital worlds feel real until now. Seems like a huge step forward for remote work and gaming.
Vishnu Vardhan Reddy M S
Oh wow great post finally someone explains why my phone vibrates differently when I get a notification vs when I play a game lol
But seriously the bit about late fusion feeling like talking through a translator is spot on. Its funny how we spent years building these silos thinking modularity was king and now we realize nuance lives in the connections.
Also kudos for mentioning bias. If your dataset is mostly English speakers with American accents good luck trying to get your AI to understand a thick Scottish brogue via voice commands. Its gonna fail hard.
Anyway keep up the good work nerd. We need more people explaining this stuff without sounding like a press release.
Onyinyechi Nwosu
the part about haptics made me think of my grandmother's hands. she could tell if fruit was ripe just by touch. ai trying to replicate that is both impressive and humbling. i hope they prioritize accessibility so everyone can benefit from these sensory experiences not just tech workers
alex kobri
we treat senses as separate inputs because we fear the chaos of integration. unified tokenization is just another way to organize the noise into silence. but who decides what constitutes signal. the machine learns our biases faster than we learn its logic. perhaps the death of late fusion is actually the birth of a new kind of blindness where everything is seen but nothing is truly understood.
Elizabeth Brooks
totally agree with the point about data silos being a nightmare for developers. its so frustrating when u have to manually link support tickets to screenshots and call recordings just to train a decent model. would love to see more tools that automate this pairing process out of the box.
also the mix of experts thing is super interesting for mobile apps. my battery dies fast enough already so any efficiency gains there are welcome.
tiffany King
This is such an encouraging look at the future! I’m particularly excited about the retail applications mentioned. Being able to visualize furniture in my own living room with accurate lighting sounds like a dream come true for anyone who hates guessing dimensions. It really highlights how technology can solve everyday frustrations.
The emphasis on ethical testing across all modalities is also crucial. As we integrate more senses into AI, ensuring fairness becomes even more complex but necessary. I appreciate the practical advice on auditing data strategies-it’s actionable steps like these that help bridge the gap between theoretical AI capabilities and real-world business value. Looking forward to seeing how smaller startups leverage these open-source tools to create innovative solutions!