• Seattle Skeptics on AI
Seattle Skeptics on AI

Tag: fair AI training
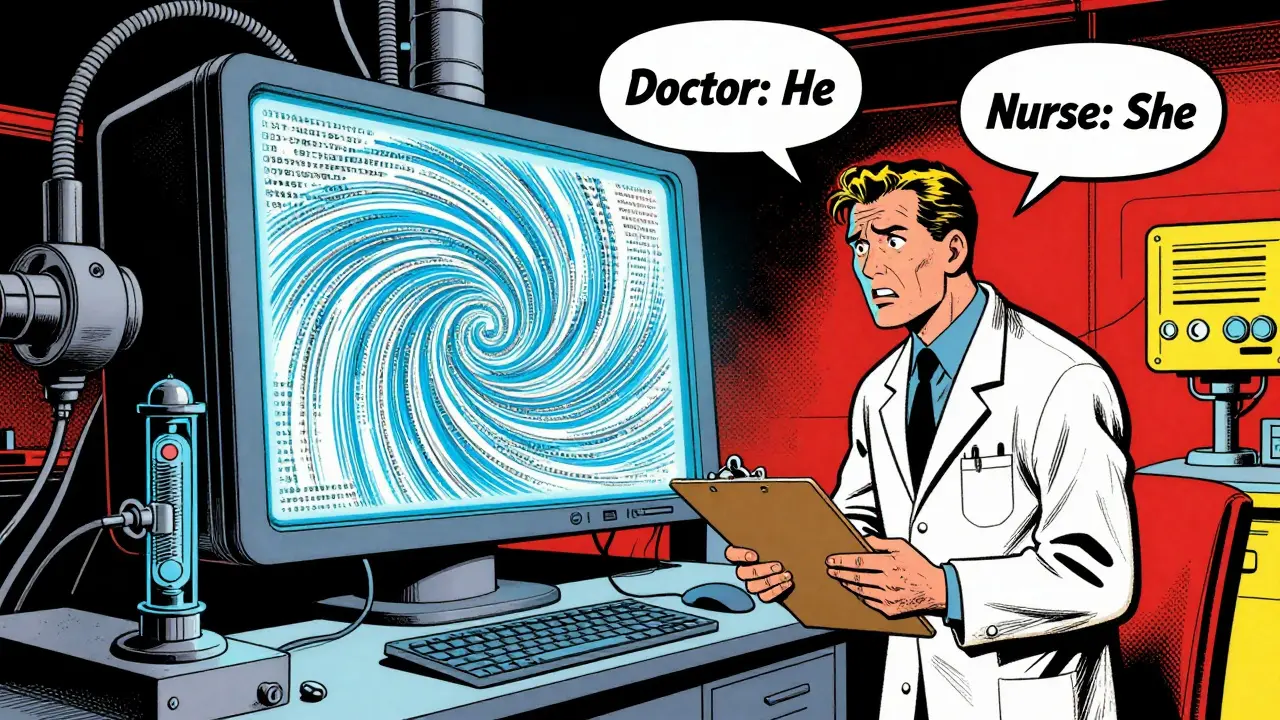
How to Fix Bias in Large Language Models: Data and Training Techniques

Tamara Weed, Jun, 23 2026

Learn practical techniques to reduce bias in Large Language Models through data augmentation, adversarial training, and post-processing. Compare costs, accuracy trade-offs, and tools for compliant AI.

Categories:

Science & Research

Tags:

LLM bias mitigation fair AI training counterfactual data augmentation adversarial debiasing AI ethics

Recent post

  • How Generative AI Transforms Construction Bids, Schedules, and Safety Plans
  • How Generative AI Transforms Construction Bids, Schedules, and Safety Plans
  • Fairness in Multilingual LLMs: Why English-Centric Alignment Fails
  • Fairness in Multilingual LLMs: Why English-Centric Alignment Fails
  • Vibe Coding for Non-Technical Founders: Build Prototypes in Days
  • Vibe Coding for Non-Technical Founders: Build Prototypes in Days
  • How to Choose Embedding Dimensionality for LLM RAG Systems
  • How to Choose Embedding Dimensionality for LLM RAG Systems
  • Mixture-of-Experts (MoE) in LLMs: Balancing Cost and Quality
  • Mixture-of-Experts (MoE) in LLMs: Balancing Cost and Quality

Categories

  • Enterprise Technology
  • Science & Research

Archives

  • October 2026
  • September 2026
  • August 2026
  • July 2026
  • June 2026
  • May 2026
  • April 2026
  • March 2026
  • February 2026
  • January 2026
  • December 2025
  • November 2025

Tags

vibe coding prompt engineering generative AI large language models transformer architecture LLM security AI governance Large Language Models prompt injection data privacy AI coding tools AI development responsible AI AI compliance AI code generation multimodal generative AI LLM optimization transformer models enterprise AI LLM architecture

© 2026. All rights reserved.